대표어
 학술연구정보서비스(KERIS)
권호기사보기
| 기사명 | 저자명 | 페이지 | 원문 | 기사목차 |
|---|
결과 내 검색
동의어 포함
Title Page 1
Contents 4
Chapter 1. Introduction 9
1.1. Research Background 9
1.2. Research Objectives 13
1.3. Research Structure 14
Chapter 2. Previous Studies on A.I. Adoption 15
2.1. Text Analysis Methods 15
2.1.1. Natural Language Processing Models 15
2.1.2. Sentiment Analysis Methods 16
2.2. Time-Series Analysis 19
2.2.1. Time-Series Feature Engineering 19
2.2.2. Statistical and Machine Learning Approaches 20
2.3. Application in E-commerce 23
2.3.1. Customer Opinion Analysis in E-commerce 23
2.3.2. Integration of Text and Time-Series Data in E-commerce 24
Chapter 3. Research Methodology 27
3.1. Overall Research Framework 27
3.2. Sentiment Analysis 29
3.3. Data Representation and Feature Engineering 33
3.3.1. Input Feature Design 33
3.3.2. Feature Engineering Strategy 37
3.3.3. Feature Selection 42
3.4. Two-Stage Ensemble Modeling Architecture 43
3.4.1. Stage-1 : Base Model 43
3.4.2. Stage-2 : Meta Model 48
3.5. Evaluation Metrics 48
Chapter 4. Experiments Design and Results 50
4.1. Dataset 50
4.1.1. Data Collection 50
4.1.2. Data Preprocessing 51
4.2. Sentiment Analysis 54
4.2.1. Experimental Design 54
4.2.2. Sentiment Analysis Results 56
4.3. Feature Engineering and Selection 57
4.4. Two-Stage Predictive Modeling 63
4.4.1. Experimental Design 63
4.4.2. Model Training and Optimization 64
4.5. Item/Category/Global-level Model Performance 64
4.6. Ensemble Model Performance 66
Chapter 5. Conclusion 69
5.1. Key Research Findings 69
5.1.1. Research Summary 69
5.1.2. Academic Implication 70
5.1.3. Practical Implication 71
5.2. Research Limitations 73
5.3. Future Works 74
Reference 75
국문요약 87
Appendices 89
Appendix A 89
Appendix B 90
Figure 1. Overall Research Framework 28
Figure 2. BERT Pre-training and Fine-tuning Procedures 29
Figure 3. BERT Input Representation 30
Figure 4. Overview of the ELECTRA Pre-training Framework 32
Figure 5. Importance of Top-10 Features Selected by XGBoost for Rating_mean... 61
Figure 6. Importance of Top-10 Features Selected by RFE for Rating mean Prediction 61
Figure 7. Importance of Top-10 Features Selected by XGBoost for Polarity_mean... 62
Figure 8. Importance of Top-10 Features Selected by RFE for Polarity_mean... 62
*표시는 필수 입력사항입니다.
| 전화번호 |
|---|
| 기사명 | 저자명 | 페이지 | 원문 | 기사목차 |
|---|
| 번호 | 발행일자 | 권호명 | 제본정보 | 자료실 | 원문 | 신청 페이지 |
|---|
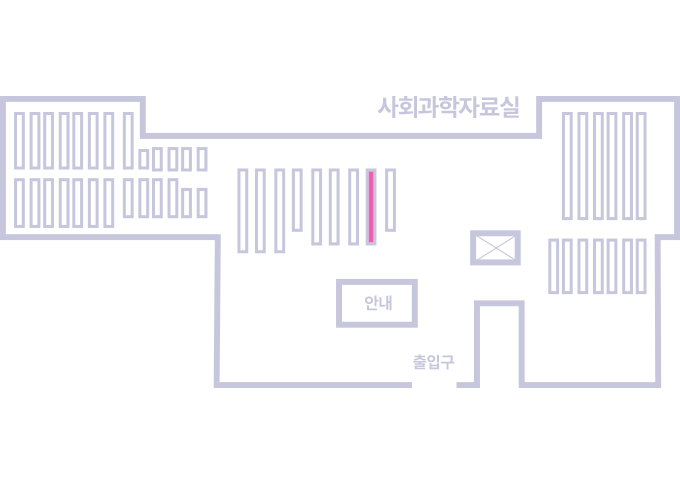
도서위치안내: / 서가번호:
우편복사 목록담기를 완료하였습니다.
*표시는 필수 입력사항입니다.
저장 되었습니다.