대표어
 한국학술지인용색인(NRF)
권호기사보기
| 기사명 | 저자명 | 페이지 | 원문 | 기사목차 |
|---|
결과 내 검색
동의어 포함
| 기사명 | 저자명 | 페이지 | 원문 | 목차 |
|---|---|---|---|---|
| 어떤 인문학적 상상력이 필요한가 : '언론학에 대한 새로운 접근으로서의 인문학'의 현실과 과제 | 박진우 | pp.4-34 |
|
|
| 언론학의 인문학적 상상력은 누구에게 무엇을 위해 필요한가 | 이영주 | pp.35-49 |
|
|
| '언론학의 인문학적 상상력은 누구에게 무엇을 위해 필요한가'에 대한 답변 | 박진우 | pp.50-57 |
|
|
| 미디어가 메시지다 : 메를로-퐁티의 현상학을 통해 살펴본 매클루언의 미디어론 | 김상호 | pp.58-98 |
|
|
| 역사와 탈역사의 경계를 넘나드는 인간 : 플루서의 커뮤니케이션 철학 | 김성재 | pp.99-126 |
|
|
| 빅데이터와 사회과학 : 인식론적, 방법론적 문제들 | 이재현 | pp.127-165 |
|
|
| 빅데이터의 문화론적 비판 : 미셀 푸코의 생정치 개념을 중심으로 | 김예란 | pp.166-204 |
|
|
| 언론학 연구방법론으로서의 구술사에 대하여 : 현장에서 길을 잃은 한 연구자의 질문과 출구 찾기 | 김세은 | pp.205-255 |
|
*표시는 필수 입력사항입니다.
| 전화번호 |
|---|
| 기사명 | 저자명 | 페이지 | 원문 | 기사목차 |
|---|
| 번호 | 발행일자 | 권호명 | 제본정보 | 자료실 | 원문 | 신청 페이지 |
|---|
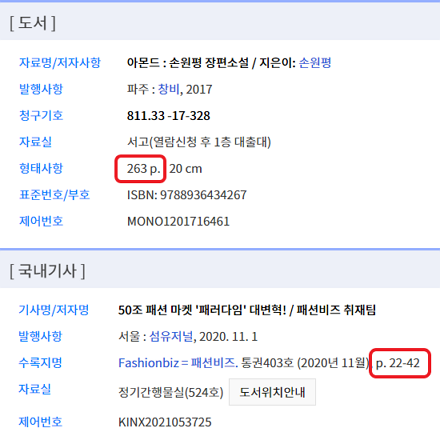
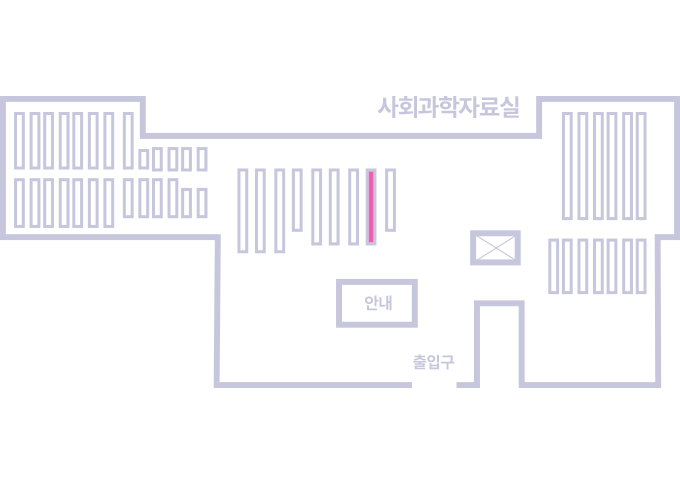
도서위치안내: 정기간행물실(524호) / 서가번호: 국내10
2021년 이전 정기간행물은 온라인 신청(원문 구축 자료는 원문 이용)
우편복사 목록담기를 완료하였습니다.
*표시는 필수 입력사항입니다.
저장 되었습니다.